Large language models (LLMs) can generate text, answer questions, summarize documents, and support many other tasks. Nevertheless, these models typically demand significant memory and computational resources. This can make them expensive and difficult to run on ordinary computers. Quantization in large language models helps address this challenge by reducing the memory needed to store model parameters. If you want to build a strong foundation in AI concepts, consider enrolling in an Artificial Intelligence Course in Vellore at FITA Academy to explore how modern AI systems work and how they are optimized.
What is Quantization in Large Language Models
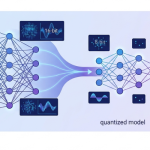
Quantization is a technique that represents model parameters using fewer bits than the original format. Model parameters are numerical values that help an AI model learn patterns and generate responses. Many models use 32-bit or 16-bit numbers during training and inference. Quantization can reduce these values to 8-bit or 4-bit formats, depending on the method used.
Using fewer bits reduces the memory required to store model weights. It can also improve processing speed and reduce hardware requirements. This makes it easier to run large language models on smaller devices and less powerful systems. However, the results depend on the model, hardware, and quantization method.
Why is Quantization Important for LLMs
Large language models may contain billions of parameters. Storing these parameters in high-precision formats requires considerable memory. For example, a model with seven billion parameters needs about 14 GB of memory just to store its weights in a 16-bit format, excluding additional memory used during operation.
Quantization reduces this storage requirement by using smaller numerical representations. It can lower hardware costs, improve accessibility, and make AI applications more practical. It is particularly useful for developers who want to run language models locally rather than relying entirely on cloud-based services.
How Does LLM Quantization Work
Quantization maps a wide range of numerical values into a smaller set of representable values. Instead of storing each parameter with high numerical precision, the model stores an approximation using fewer bits.
The process may involve scaling and rounding values to fit the selected numerical format. Some methods quantize model weights alone, while others also quantize activations, which are intermediate values produced during computation.
There are two common approaches. Post-training quantization is applied after a model has been trained. Quantization-aware training incorporates quantization effects during training to help the model adapt to reduced precision. The suitable approach hinges on the model and the intended equilibrium between performance and precision.
Types of Quantization Used in Large Language Models
8-Bit Quantization
Eight-bit quantization uses fewer bits than common 16-bit formats while often preserving much of the model's original quality. It can be a useful choice when memory savings are important, but accuracy remains a priority.
4-Bit Quantization
Four-bit quantization provides greater memory savings by representing parameters with even fewer bits. It can make large models practical on consumer hardware, although some tasks may experience a greater loss in accuracy.
Mixed-Precision Quantization
Mixed-precision quantization uses different numerical formats for different parts of a model. Sensitive components can retain higher precision, while other components use fewer bits. This approach aims to balance efficiency and output quality.
If you want to understand how these optimization methods fit into practical AI development, take an Artificial Intelligence Course in Erode to explore machine learning models, their performance, and the techniques used to make them more efficient.
Benefits and Challenges of Quantization
Quantization offers several advantages. It reduces model memory requirements, may increase inference speed, and can lower energy consumption. It also makes it possible to deploy language models on devices with limited hardware resources.
However, quantization can introduce errors because numerical values become less precise. These errors may affect response quality, reasoning, or performance on specific tasks. Speed improvements are not guaranteed because they depend on hardware support and the software used to run the model.
Testing is therefore essential. Developers should compare the quantized model with the original model using relevant evaluation tasks. They should also measure memory usage, response quality, and inference speed before choosing a quantization method.
Quantization is an important technique for making large language models smaller and more accessible. By decreasing the number of bits allocated for model parameters, it can minimize memory needs and enhance deployment effectiveness. The best approach depends on the model, available hardware, and acceptable accuracy trade-offs.
As AI continues to evolve, understanding model optimization will become increasingly valuable for learners and developers. If you are ready to expand your knowledge of machine learning and modern AI technologies, explore an Artificial Intelligence Course in Villupuram to develop your understanding of AI fundamentals and practical applications.
Also check: Understanding What Makes a System Intelligent